§ 08 / schedule · long talk
Removing the Human Bottleneck in Model Fine-Tuning/Pre-Training with RLAIF
§ 01 / abstract
About the talk.
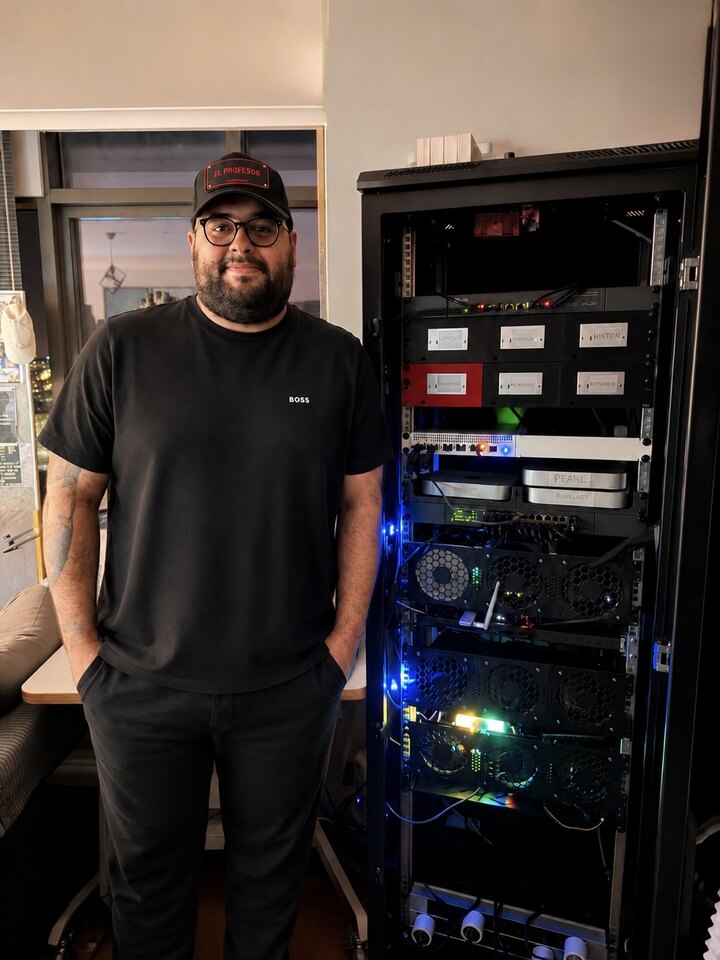
With Reinforcement Learning from AI Feedback (RLAIF), we can now create Instruct- and SFT-based reinforcement learning loops for models with minimal reliance on human data. This allows models to train without human involvement in a teacher/student structure, without requiring human feedback. With the setup I built in my own homelab, I can develop my Turkish-language open-source LLM and VLM models for finance, law, and cybersecurity 24/7, with minimal human interaction.
§ 02 / speaker
On stage.
§ 03 / in the running order
Where it sits in the day.
-
Self-Healing a GPU Fleet at Scale
Daglar Berk Erdem · FAL.ai
short talk · 20 min Turkish Sign Language interpretationTR Turkish Sign Language interpretation - Break 20 min
-
Removing the Human Bottleneck in Model Fine-Tuning/Pre-Training with RLAIFthis talk
Alican Kiraz · Trendyol
long talk · 40 min Turkish Sign Language interpretationTR Turkish Sign Language interpretation -
Run the Dark Code: Why Your Agent's Error Handling Has Never Executed - and How to Run It on Purpose
Cenk Kalpakoglu · Invicti
short talk · 20 minEN -
Developing and Running AI Models in Critical Systems: How Do We Design Explainable, Auditable, and Reliable Models?
Fatih Bildirici · ASELSAN
short talk · 20 min Turkish Sign Language interpretationTR Turkish Sign Language interpretation